oMLX
Mac local large model inference service
Introduction
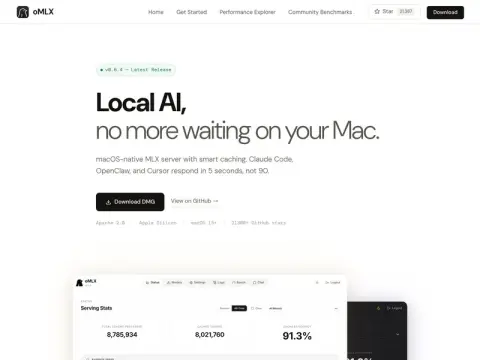
oMLX is a macOS native inference server based on MLX and specially optimized for running local models on Mac.
The pain point it targets is very clear: the coding agent will repeatedly invalidate the KV cache in a session, and the prompt must be recalculated from the beginning each time, and the waiting time can reach 30 to 90 seconds. oMLX's approach is to persist cache blocks to SSD in safetensors format. Hot blocks remain in memory and cold blocks are moved to disk according to LRU. The prefixes seen before can be restored from disk in milliseconds and are valid across requests and even across server restarts. The official result is that after the second round, the first character delay was reduced to less than 5 seconds.
The API is compatible with OpenAI and Anthropic formats, and Claude Code, OpenClaw, and Cursor can all be directly referenced. The project uses the Apache 2.0 protocol and requires Apple Silicon and macOS 15 and above.
It is suitable for developers who have a Mac with large memory and want to move the inference of the coding agent locally.